
String vs Browserbase (2026): 100 bot-protected sites tested
Which is better, String or Browserbase?
Browserbase is browser infrastructure and String is page retrieval. Browserbase sells hosted Chrome sessions for agents that click, log in, and fill forms, plus a lighter Fetch API. String sells one endpoint that fetches protected pages. On the Web Data Frontier Benchmark of 100 bot-protected sites (October 30, 2026), String returned verified content on 98.6% of requests and Browserbase's Fetch API, with proxies on, 43.0%. String's latency score was 4.24 seconds (first of 17) and Browserbase's 18.01 (eighth). Pick Browserbase for a login, a form, or a multi-step flow. Pick String for reading a page that fights back.
- Choose String if the job is reading pages that block bots. String returned 98.6% of requests and Browserbase's Fetch API 43.0%.
- Choose Browserbase if an agent has to log in, fill a form, or click through a flow. That is browser work, and Browserbase is built for it.
- Do not switch if your workload depends on hosted sessions, recordings, or live view. Keep Browserbase for those and move only the page reads that fail.
TL;DR
- Success rate: String 98.6%, Browserbase Fetch API 43.0% (100 sites, 5 attempts each, October 2026)
- Latency score: String 4.24s (1st of 17), Browserbase 18.01s (8th)
- Cloudflare-protected targets: String 98.7%, Browserbase 6.7%
- Sites where nothing came back: String 0, Browserbase 53
- Social platforms: tie, 40/40 each
- Browserbase's own guidance agrees on the split: use Fetch when you do not need to click, and a browser only when the page demands one
- Every number comes from a public harness you can re-run with your own API keys
| String | Browserbase | |
|---|---|---|
| Product type | Unblocker: fetch, search, sitemap, remote browser over CDP | Browser infrastructure: hosted browser sessions, agents, Fetch, Search, Extract |
| Benchmark success rate | 98.6% (493/500) | 43.0% (215/500), Fetch API with proxies |
| Latency score, all 17 providers | 4.24s (1st) | 18.01s (8th) |
| Sites where nothing came back | 0 of 100 | 53 of 100 |
| Social platforms (8 targets) | 40/40 | 40/40 |
| Pricing basis | Pay per successful request; rate set by the proxy and fetch path the page needed; credits roll over | Subscription plus per-call Fetch ($1 or $0.50 per 1,000; $4 with proxies), browser hours ($0.10 to $0.12 per hour overage), proxy bandwidth ($10 to $12 per GB) |
| Browser support | Browser fetch path billed per request; /wss remote Chrome over CDP | Core product: hosted Chrome sessions, up to 250+ concurrent on Scale, Stagehand framework |
| JS rendering | Yes, selected per request | Yes, in browser sessions; Fetch is the lightweight path |
| Anti-bot coverage (benchmark) | 100% AWS WAF, Kasada, Fastly; 98.7% Cloudflare; 97.9% DataDome; 97.8% PerimeterX; 97.0% Akamai | 6.7% Cloudflare; 28.0% Akamai; 31.6% DataDome; 73.3% PerimeterX; 33.3% Kasada |
| MCP and agent integrations | Registry ai.usestring/web-access, hosted at mcp.usestring.ai; fetch, search, sitemap tools |
MCP server, Stagehand, agent SDKs, hosted runtime functions |
| Where it wins | Protected pages; pay-on-success billing; latency score | Interactive browser work; social platforms (tie); SOC 2 on every plan, HIPAA on Scale |
How we tested, and our conflict of interest
We built the Web Data Frontier Benchmark and we sell the product that ranks first in it. The answer to that conflict is a test you can run yourself: the harness, the 100 target URLs, the pass criteria, and every provider's adapter are public, and the repo takes your own API keys. Providers have used that path: a Firecrawl engineer corrected our Firecrawl adapter in July, and the September run corrected our ScraperAPI and ScrapingBee adapters, moving those two by 19.8 and 43.3 points. Browserbase can do the same.
The Browserbase adapter matters here, so read it before you read the numbers. It calls Browserbase's Fetch API with proxies: true, which is the product shape closest to String's fetch endpoint and the path Browserbase's own docs recommend for reading a page you do not need to interact with. Since the October run it no longer retries inside Browserbase's SDK, so each attempt is one request. It does not open a browser session, and it does not use the Verified fingerprints Browserbase reserves for its Scale plan. A browser session might clear more of these sites. It would also cost browser hours instead of a per-call fee. If Browserbase believes a different configuration is fairer, the adapter is one short file and a pull request changes it.
Every figure below comes from the October 30, 2026 run's results JSON, written up in the October 2026 benchmark post. Pricing and billing terms were checked against both companies' live pages on August 29, 2026.
What each product is
Browserbase is a platform for running browsers in the cloud: browser sessions with live view and recordings, an agents layer, a hosted runtime for functions, a Search API for finding pages, a Fetch API for reading them without a browser, an Extract API, and an identity layer of proxies, contexts, and Verified fingerprints. It maintains Stagehand, an open-source browser automation framework, and ships an MCP server. If your agent has to log in, click through a wizard, or fill a form, this is the tooling built for it.
String is one endpoint. Send a URL, get the page back as markdown, HTML, or JSON. Proxy rotation, fingerprinting, captcha solving, and retries happen behind the endpoint. There is a /search endpoint for live Google results, an asynchronous sitemap crawl, a /wss endpoint for a remote browser over CDP when you need one, and an MCP server at mcp.usestring.ai. String does not sell a browser-agent platform. Browserbase has more product; String holds up on pages that fight back.
Browserbase's own writing draws the same line. Its post on choosing between Search, Fetch, and Browser says to use Fetch when you do not need to click, scroll, or log in, and that reliable agent teams "do as much as possible with lightweight primitives" and reach for a browser only when the page demands one. The benchmark measures the lightweight primitive.
The same request in Browserbase and String
One job, done both ways: fetch a JavaScript-heavy product page and get its content back. Each request follows the vendor's own docs for that job, checked against those docs on October 15, 2026. Each one reads its key from an environment variable, such as $STRING_API_KEY.
curl -X POST https://api.browserbase.com/v1/fetch \
  -H "Content-Type: application/json" \
  -H "X-BB-API-Key: $BROWSERBASE_API_KEY" \
  -d '{"url": "https://www.example.com/product/123", "proxies": true}'
curl https://request.usestring.ai/v1/fetch \
  -H "Authorization: Bearer $STRING_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"url": "https://www.example.com/product/123", "format": "markdown"}'
Browserbase's Fetch API is the closest match and is the path the benchmark tested. It returns a JSON envelope with the page in content, does not run JavaScript, caps pages at 5 MB, and does not follow redirects unless you set allowRedirects. For a page that needs JavaScript, Browserbase's docs move you to a browser session: create one, connect Playwright over CDP, load the page, and read page.content(). String's one request covers both cases, because the API decides per request whether to load the page in a browser. Add "executeJS": true if you want to force one.
Success rate: String 98.6%, Browserbase 43.0%
The benchmark sends 17 providers the same 100 URLs, 5 attempts each, every provider in its strongest fetch mode: 8,500 live billable requests. A request passes only when the response contains a marker from the real page, such as a product title. A captcha page that returns HTTP 200 counts as a failure. Most targets are bot-protected retail, travel, news, and social sites.
| Provider | Success rate | Latency score |
|---|---|---|
| String | 98.6% | 4.24s |
| Scrape.do | 94.0% | 5.08s |
| Context.dev | 93.0% | 10.96s |
| Scrapfly | 86.8% | 19.62s |
| ScrapingBee | 85.2% | 20.30s |
| Firecrawl | 81.2% | 8.87s |
| Zyte | 79.6% | 14.43s |
| Apify | 79.4% | 24.87s |
| ScraperAPI | 76.4% | 15.19s |
| Bright Data | 75.4% | 27.88s |
| Decodo | 71.2% | 28.29s |
| Nimble | 68.0% | 22.65s |
| Oxylabs | 67.4% | 16.62s |
| Browserbase | 43.0% | 18.01s |
The latency score is a per-target p75 of successful attempts. A provider that returns nothing on a target inherits the p75 of the providers that did succeed there, and if nobody succeeds the target scores the 90-second timeout. The score refuses to reward fast failures. Browserbase's 18.01 seconds is eighth of 17, mid-field, and String's 4.24 leads the run; Scrape.do follows at 5.08.
This benchmark measures one thing: whether a fetch returns the real page from a protected site. It does not measure what Browserbase is mostly bought for, which is running an agent through a multi-step browser task. Browserbase publishes its own reliability figures for that work on its site; they come from Browserbase's own runs, and this page does not use them.
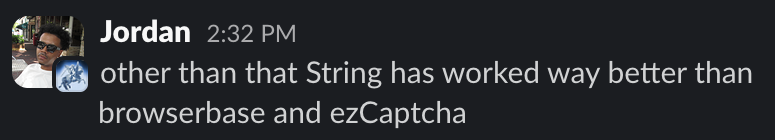
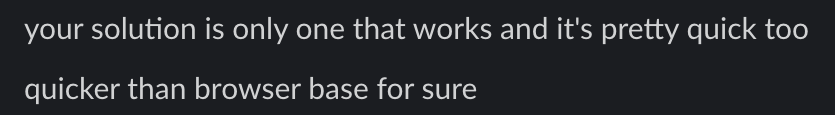
What customers say after switching from Browserbase
other than that String has worked way better than browserbase and ezCaptcha
your solution is only one that works and it's pretty quick too
quicker than browser base for sure
Jordan, a String customer that moved from Browserbase, on Slack.
Where Browserbase fails: 53 sites returned nothing
The 43.0% average hides where the failures sit. Per target, Browserbase's Fetch API is either fine or absent.
| Per-target outcome (100 sites) | String | Browserbase |
|---|---|---|
| Passed all 5 attempts | 95 | 35 |
| Passed some attempts | 5 | 12 |
| Passed none | 0 | 53 |
The 53 sites where Browserbase returned nothing on any attempt include Temu, Home Depot, Lowe's, Best Buy, Kroger, eBay, Nike, Lululemon, Zara, Louis Vuitton, Saks Fifth Avenue, StockX, Yelp, G2, Capterra, Trustpilot, Glassdoor, ZipRecruiter, Realtor.com, Apartments.com, Zoopla, Idealista, Tripadvisor, Kayak, Delta, American Airlines, Hyatt, Booking.com, AutoZone, StubHub, AXS, Congress.gov, Crunchbase, DigiKey, Roblox, GitHub, and Stack Overflow. String passed 50 of the 53 on all five attempts. The other three were String's own weak spots: Skyscanner and Yellow Pages at 4 of 5, and Kroger at 2 of 5.
Browserbase beat String on no target in this run. The two tied on 36: the 35 sites both passed in full, plus MarketWatch at 4 of 5 each.
Some of those shutouts are policy, not capability
Browserbase's proxy documentation says its built-in residential proxies come from third-party providers, and that those providers restrict certain site categories under their own acceptable-use rules. Browserbase names the categories: banking and financial services, government domains including most .gov sites, streaming and entertainment, ticketing, webmail, and gambling. It adds that support "isn't a blanket yes/no per site" and tells you to test your own targets first.
Three results on this page sit inside those categories. Congress.gov is a .gov domain, and StubHub and AXS are ticketing. All three returned nothing. That is worth saying plainly: on those targets the benchmark is measuring a proxy-provider policy, not a limit of Browserbase's engineering. It is also worth saying that the distinction does not help a buyer whose target list includes ticketing or government pages, because the pages still do not come back.
Cloudflare: String 98.7%, Browserbase 6.7%
Fifteen of the 100 targets sit behind Cloudflare. String passed 74 of the 75 requests against them. Browserbase's Fetch API passed 5 of 75, or 6.7%. Akamai is similar: 28.0% for Browserbase across 20 targets, 97.0% for String. DataDome, the largest named column at 19 targets, is 31.6% to 97.9%. The only anti-bot vendor where Browserbase clears more than half its requests is PerimeterX, at 73.3%, where String returned 97.8%.
For anyone whose target list is retail, fashion, or travel, this is the evaluation. Those industries are where Cloudflare, Akamai, and DataDome live, and the industry cut says the same thing: fashion and luxury 32.7% to 100%, travel 22.2% to 97.8%, retail and ecommerce 36.5% to 100%, reviews and local 0% to 96.7%.
Social platforms: a tie at 40/40
Eight of the 100 targets are social platforms: LinkedIn, X, Instagram, Reddit, TikTok, Facebook, Pinterest, and YouTube. Both providers passed all 40 requests. Firecrawl, by contrast, passed 10 of 40 and blocks several of these platforms by policy. If public social pages are your workload, Browserbase's Fetch API is a credible option, and String's advantage over it is elsewhere.
Flaky targets corrupt datasets quietly
The 53 shutouts are visible within an hour of testing. The more expensive problem is the 12 sites where Browserbase passed some attempts and failed others:
| Target | Browserbase | String |
|---|---|---|
| SeatGeek | 1/5 | 5/5 |
| Ralph Lauren | 3/5 | 5/5 |
| Etsy | 3/5 | 5/5 |
| Amazon | 3/5 | 5/5 |
| Bloomberg | 3/5 | 5/5 |
| Barron's | 3/5 | 4/5 |
| MarketWatch | 4/5 | 4/5 |
| Ashley Furniture | 4/5 | 5/5 |
| GoodRx | 4/5 | 5/5 |
| Vinted | 4/5 | 5/5 |
| Leboncoin | 4/5 | 5/5 |
| Walmart | 4/5 | 5/5 |
A scheduled job that clears SeatGeek one attempt in five looks alive in monitoring while it starves the dataset: gaps in time series, values that appear to move because a scrape silently missed. Retries paper over the problem and inflate the bill, and Browserbase bills Fetch per call.
Speed: String is faster on the score, and the gap is not the point
String's latency score of 4.24 seconds leads the run; Browserbase's 18.01 is eighth of 17. The score charges a provider for the targets it fails, and Browserbase tied ZenRows for the most sites with nothing returned, so its score is not a measure of how fast a Browserbase fetch is when it works. On the 35 sites both products returned in full, the median per-site time was 1.11 seconds for String and 1.86 for Browserbase, both under two seconds. On the pages it does return, a Fetch call is a lightweight HTTP path and is quick. If speed on cooperative pages is your question, both products are fast enough that success rate should decide it.
Pricing: per-call plus subscription vs pay per success
Browserbase sells a subscription with allocations and pay-as-you-go overage. Free is $0 with 1 browser hour, 1,000 Fetch calls, and no proxies. Developer is $20 a month with 100 browser hours (then $0.12 per hour), 1 GB of proxy bandwidth (then $12 per GB), 25 concurrent browsers, and 1,000 Fetch calls, then $1 per 1,000. Startup is $99 with 500 browser hours (then $0.10 per hour), 5 GB of proxies (then $10 per GB), 100 concurrent browsers, and 10,000 Fetch calls, then $0.50 per 1,000. Fetch through proxies costs $4 per 1,000 calls on both paid plans, and proxies are what protected sites need. Search is $7 per 1,000 after the first 1,000. Verified fingerprints and 250+ concurrency are on the custom Scale plan.
String's plan fee is paid in as usage credit. The first 20,000 standard fetches are free. Starter is $19 a month and includes $19 of usage; Growth is $99 and includes $99. Usage above that bills at the same rates. The per-request rate depends on what the page actually needed:
| Fetch path and proxy | Starter, per 1,000 | Growth, per 1,000 |
|---|---|---|
| Request-based, standard proxy | $0.25 | $0.16 |
| Request-based, premium proxy | $2.40 | $0.90 |
| Browser-based, standard proxy | $1.20 | $0.80 |
| Browser-based, premium proxy | $4.80 | $3.25 |
Unused credit rolls over on every plan, and a blocked request is never billed.
On the headline rate, Browserbase's proxied Fetch at $4 per 1,000 calls is above all four of String Growth's paths, including the $3.25 browser-on-premium-proxy path. The fairer unit is cost per 1,000 usable pages, which folds in the benchmark pass rate. At 100,000 requests a month against the benchmark suite:
| Billing assumption | Cost per 1,000 usable pages | |
|---|---|---|
| Browserbase Startup, Fetch with proxies | $99 plus $4 per 1,000 calls; 43.0% return content; every call bills | $11.60 |
| Browserbase Startup, Fetch with proxies, if the 10,000 included calls apply | $99 plus $4 per 1,000 for 90,000 calls | $10.67 |
| String Growth, standard request | 98,600 successes at $0.16 per 1,000 is $15.78, inside the $99 fee; failures free | $1.00 |
| String Growth, premium request | 98,600 successes at $0.90 per 1,000 is $88.74, inside the $99 fee | $1.00 |
| String Growth, browser on premium proxy | 98,600 successes at $3.25 per 1,000 is $320.45, above the $99 fee | $3.25 |
Two caveats on that table, both in Browserbase's favor. Browserbase's billing pages price Fetch per call throughout, never per successful call, and as of August 29, 2026 they name no exclusion for a fetch that fails or comes back blocked. So the table assumes every call bills. That is what their published terms say rather than something they state outright, and if Browserbase does credit failed fetches, its numbers fall. The second caveat is that a Browserbase browser session, billed in browser hours, is a different product with a different pass rate that this benchmark did not measure. What the table does say is that on protected pages the Fetch API's price per usable page is set by its 43.0% pass rate, and no plan tier changes that.
The risk asymmetry follows from that reading: on published terms your evaluation bills at $4 per 1,000 calls whether or not the page comes back. String's evaluation bills nothing for a block, and the first 20,000 standard fetches are free.
One throughput note that does not show up in a price table. Browserbase caps Fetch at 5 requests per second per project on every plan, Free through Startup, with a custom rate only on Scale. At that ceiling, 100,000 pages takes about five and a half hours of continuous calling even if every call succeeds. If your workload is a nightly bulk read, check that number against your window before you check the price.
Which to pick, by job
- Retail, fashion, and grocery pages: String. Browserbase's Fetch API returned nothing from Home Depot, Lowe's, Asda, Best Buy, Nike, Zara, or Louis Vuitton, and passed Walmart 4/5. String passed all of them 5/5. Kroger returned nothing from Browserbase and 2/5 from String.
- Travel: String. Browserbase returned nothing from Kayak, Delta, American Airlines, Hyatt, Tripadvisor, Skyscanner, or Booking.com. String passed six of those seven 5/5 and Skyscanner 4/5. Expedia and Airbnb were 5/5 for both.
- Reviews and local: String. Yelp, G2, Capterra, Trustpilot, and Yellow Pages all returned nothing from Browserbase; String passed Yellow Pages 4/5 and the other four 5/5.
- News and finance: mixed. Browserbase cleared Yahoo Finance, WSJ, TradingView, CoinMarketCap, and The New York Times perfectly and passed 77.8% of the category; MarketWatch was 4 of 5, Bloomberg and Barron's 3 of 5, and Reuters returned nothing. String passed 95.6%: seven of the nine 5 of 5, and MarketWatch and Barron's 4 of 5.
- Social platforms: either. Both passed 40 of 40.
- Ticketing: String. Ticketmaster was 5/5 for both and SeatGeek 1/5 for Browserbase; StubHub and AXS returned nothing from Browserbase.
- Developer and research pages: String, with a surprise. GitHub and Stack Overflow, the two cooperative pages in the suite, returned nothing from Browserbase's Fetch API on any attempt. arXiv passed 5/5 for both.
- Anything an agent has to drive: Browserbase. Logging in, filling a form, clicking through a booking flow, or reading a page whose content only exists after interaction is browser work. String's /wss endpoint gives you a remote browser when you need one, but Browserbase's sessions, recordings, live view, contexts, and Stagehand are the platform for that job.
- Agent web access over MCP: depends on the target list. Both ship MCP servers. An agent that browses and acts is well served by Browserbase; an agent that reads protected pages needs String behind it.
Switching from Browserbase to String
What carries over. Browserbase's own guidance is Search, then Fetch, then a browser only when the page needs one. String replaces the Fetch step. POST /v1/fetch with X-BB-API-Key becomes a POST to https://request.usestring.ai/v1/fetch with Authorization: Bearer, the same url field, and "format": "markdown". Playwright or Puppeteer code that only loads a page and reads its HTML can become one fetch call. Code that needs a browser can connect to String's remote browser over CDP.
What you rebuild. Contexts with saved logins, live view, session recordings, Functions, the Agents API, Verified fingerprints, and Stagehand. String's remote browser is a CDP endpoint for Playwright or Puppeteer. If your agents log in or drive multi-step flows, keep those sessions on Browserbase, and running both is a reasonable end state.
Integrations to reconnect. Browserbase publishes Node.js and Python SDKs, Stagehand, an MCP server, an n8n community node, and integrations for LangChain, the Vercel AI SDK, CrewAI, Mastra, and many other agent frameworks. String ships no language SDK, so an SDK call becomes one HTTP POST. Its hosted MCP server runs at mcp.usestring.ai, n8n calls String through the HTTP Request node, and Zapier, LangChain, and the Vercel AI SDK have setup guides in String's docs.
Test on your own failing URLs first. Take the URLs your Fetch calls fail on today and run them through String first. In this run Browserbase's Fetch API returned nothing on 53 of the 100 sites, and String returned 50 of those on every attempt. Compare pages returned and cost per usable page, then move only the targets that improve. Leave custom headers off for the test: String does not bill a blocked request unless that request sent custom headers. The first 20,000 String standard fetches are free with no card. If you are weighing more than two tools, the ranking of 17 web scraping APIs uses the same benchmark.
FAQ
String vs Browserbase: what is the actual difference?
Browserbase is browser infrastructure: hosted Chrome sessions for agents that click, log in, and fill forms, plus Fetch and Search APIs for reading and finding pages. String is a fetch endpoint that gets protected pages back and bills only when content returns. On the open Web Data Frontier Benchmark (100 bot-protected sites, October 2026), String passed 98.6% of requests and Browserbase's Fetch API, with proxies, passed 43.0%.
Is Browserbase good for web scraping?
For pages that need interaction, yes; that is what it is built for. For bulk reads of protected pages, the benchmark says no: Browserbase's Fetch API returned nothing on 53 of 100 bot-protected sites, tied with ZenRows for the most of any provider in the run, and passed 6.7% of requests against Cloudflare-protected targets. Browserbase's own guidance is to use Fetch for simple pages and a browser only when the page demands one.
Does Browserbase get past Cloudflare?
Not through its Fetch API in this run. On 15 Cloudflare-protected targets, Browserbase passed 5 of 75 requests; String passed 74 of 75. Akamai was 28.0% to 97.0% and DataDome 31.6% to 97.9%. A Browserbase browser session with Verified fingerprints (Scale plan) was not tested.
Do I need a headless browser to scrape protected sites?
Usually not. The benchmark's top three, String at 98.6%, Scrape.do at 94.0%, and Context.dev at 93.0%, are fetch APIs, not browsers you drive. String bills the browser path only when it used one ($0.80 to $3.25 per 1,000 on Growth) and the plain-fetch path otherwise ($0.16). You need a browser you control when the task is interaction, and that is Browserbase's product.
Is Browserbase cheaper than String?
Not for reading protected pages. Browserbase's Fetch API is $1 or $0.50 per 1,000 calls without proxies and $4 per 1,000 with them, on top of a $20 or $99 subscription. String Growth is $0.16 per 1,000 for a plain fetch and $0.80 to $3.25 when a page needs a browser or a premium proxy. Per usable page at 100,000 requests a month against the benchmark suite, Browserbase's proxied Fetch works out to $10.67 to $11.60 per 1,000 at its 43.0% pass rate; String's standard and premium request paths are $1.00, both inside the $99 Growth fee, and its most expensive path $3.25. For browser sessions, Browserbase bills hours ($0.10 to $0.12 per hour overage), which is a different unit and a different job.
Does Browserbase charge for failed requests?
Browserbase prices Fetch per call ($1, $0.50, or $4 per 1,000) and browser sessions per hour; its docs describe allocations and overage, not a success-only rule. String bills only requests that return verified content, so a block costs nothing.
When should I use Browserbase instead of String?
When the job is a browser job: authenticated flows, forms, multi-step interactions, pages whose content only appears after a click, or an agent that has to act rather than read. Browserbase's sessions, Stagehand, contexts, and Verified fingerprints are built for that, and its Fetch API passed every social-platform request in the benchmark. Use String when the job is getting a protected page back reliably.
How can I verify these numbers?
Run the benchmark. The harness, 100 target URLs, pass criteria, and per-provider adapters, including the Browserbase adapter that calls Fetch with proxies, are public at github.com/usestring/web-data-frontier-benchmark, and it takes your own API keys. A full run makes thousands of billable calls, so start with a subset. If your numbers differ, or if Browserbase's team thinks a different configuration is fairer, open a pull request; Firecrawl did, and their score went up.